Removing Occlusion Errors in ToF Camera Depth Completion Using Stereo-Aware Augmentation
June 15, 2023
This article introduces how we tackle occlusion errors in depth completion caused by stereo calibration, without requiring raw sparse depth data.
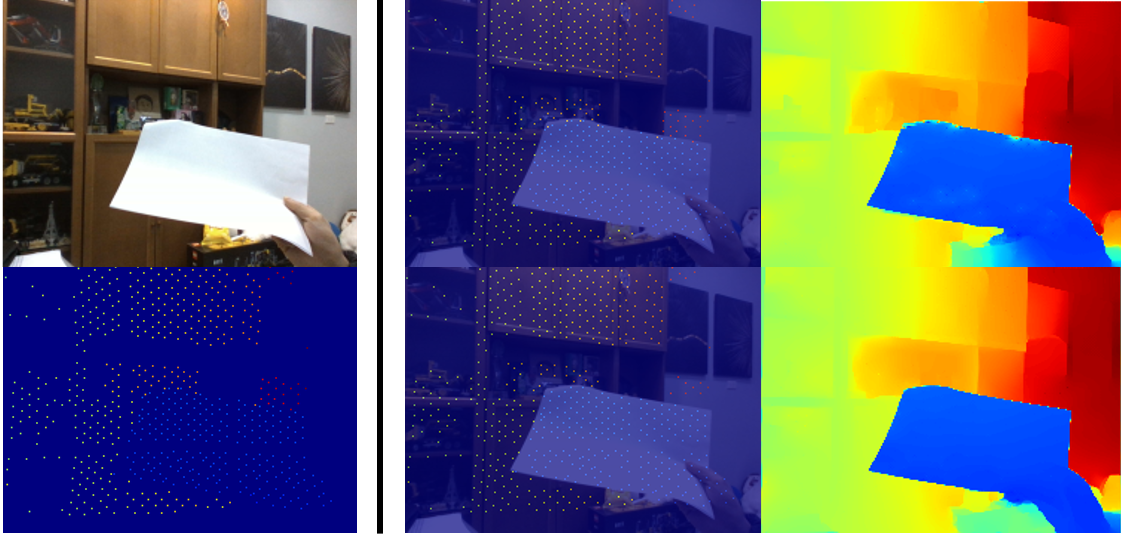
Fig. 1: Removing occlusion errors in ToF depth maps. Given a color image and a sparse depth map (first column), we overlay the two images to visualize the impact of occlusion errors caused by dual-camera calibration (top of the second column), and show the sparse depth masked by the estimated confidence mask (bottom of the second column). The state-of-the-art depth completion model EMDC [2] benefits from our method (third column).
In this article, we propose a method for addressing occlusion errors in depth completion caused by stereo calibration. Our unsupervised training procedure, not relying on any ground-truth data, combines pseudo labels generation and confidence estimation to reduce the amount of error introduced into the depth map for depth completion. Occlusion errors in depth completion refer to situations where the model incorrectly estimates the depth of an object that is partially or fully obscured by another object. This can happen when the model is not able to fully understand the context of the scene and the relationships between different objects. Occlusion errors can lead to inaccuracies in the final depth map and can negatively impact the performance of downstream tasks that use the depth information, such as object detection and tracking. As shown in Fig. 1, our experimental results demonstrate the effectiveness of our approach in reducing occlusion errors while retaining the overall accuracy of the depth map.
Introduction
The goal of depth completion is to complete the depth channel of an RGB-D image. In order to establish a precise relationship between two camera coordinate systems, stereo calibration estimates the intrinsic and extrinsic parameters of a pair of cameras, establishing accurate correspondence between their image coordinates. This relationship is crucial for many applications in computer vision. However, stereo calibration usually induces negative effects such as occlusion errors, which typically arise when certain parts of the scene or objects are obstructed or hidden from one of the cameras. There are several ways to address occlusion errors caused by stereo calibration in depth completion: 1) multi-view depth completion — by using multiple views of the same scene, the model can better understand the context of the scene and the relationships between objects, which helps reduce occlusion errors; 2) attention-based models, which are able to focus on specific parts of the input, helping the model better understand the relationships between objects and reduce occlusion errors; and 3) adversarial training, which can improve the robustness of the model to occlusion by training it to generate realistic depth maps even when occlusions are present in the scene.
There have been several prior works on addressing occlusion errors. [1] estimates confidence in LiDAR depth maps in an unsupervised manner and predicts the uncertainty of the depth values. This method, however, requires an existing dataset that provides raw depth maps with occlusion errors and expensive annotations, such as KITTI [3]. Unfortunately, no Time-of-Flight (ToF) dataset satisfies these assumptions. It is worth noting that no single method is likely to be a complete solution to the occlusion problem in depth completion; often, a combination of methods is used to address occlusion errors.
Problem Formulation
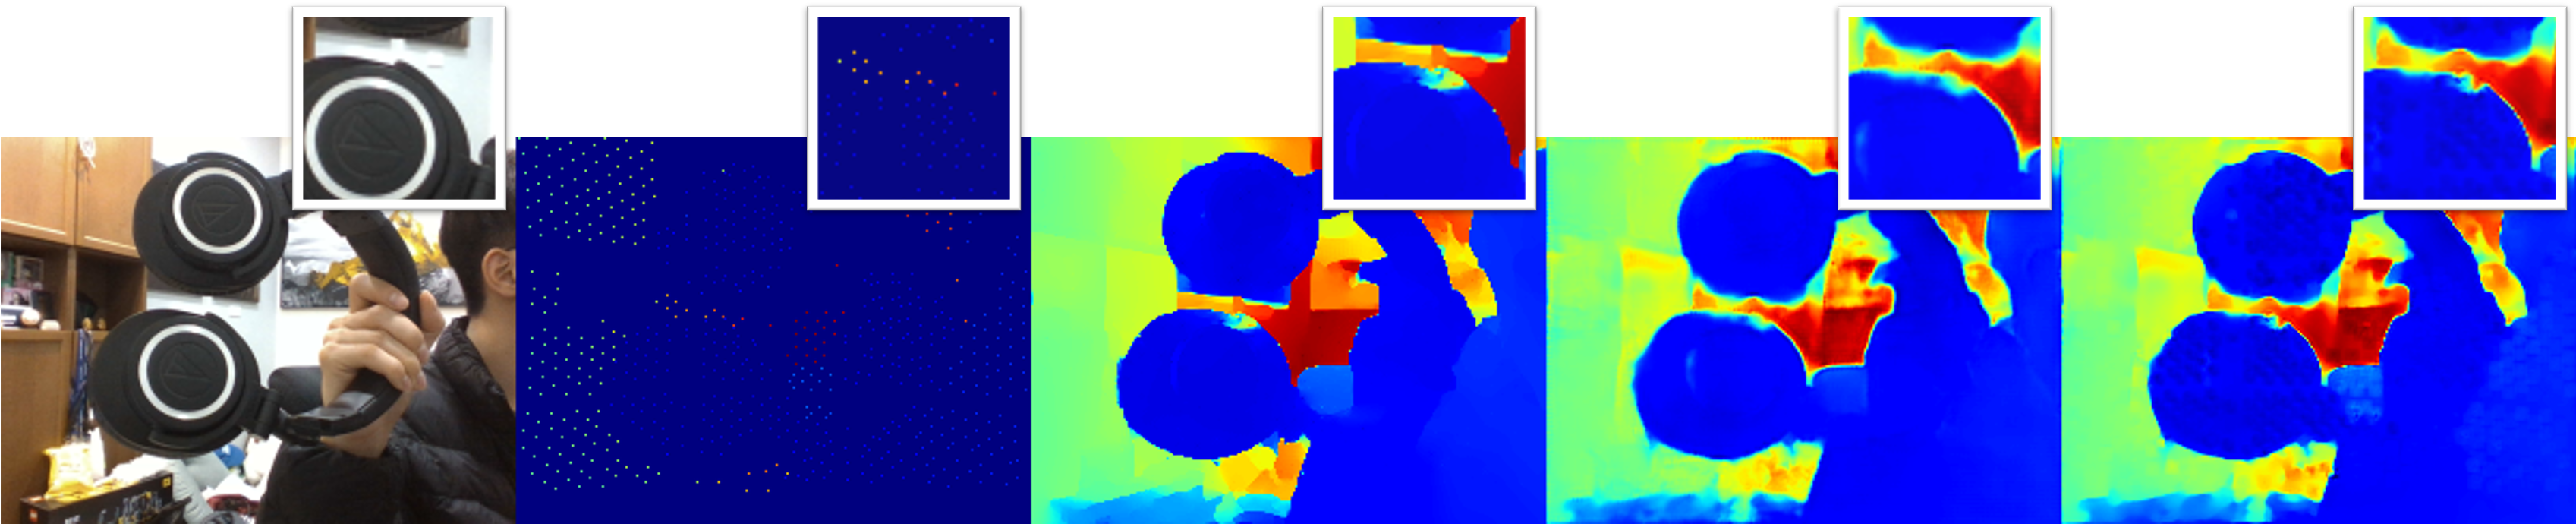
Fig. 2: Occlusion errors degrade the results of the state-of-the-art depth completion method EMDC [2].
The impact of occlusion errors is illustrated in Fig. 2.
Proposed Model
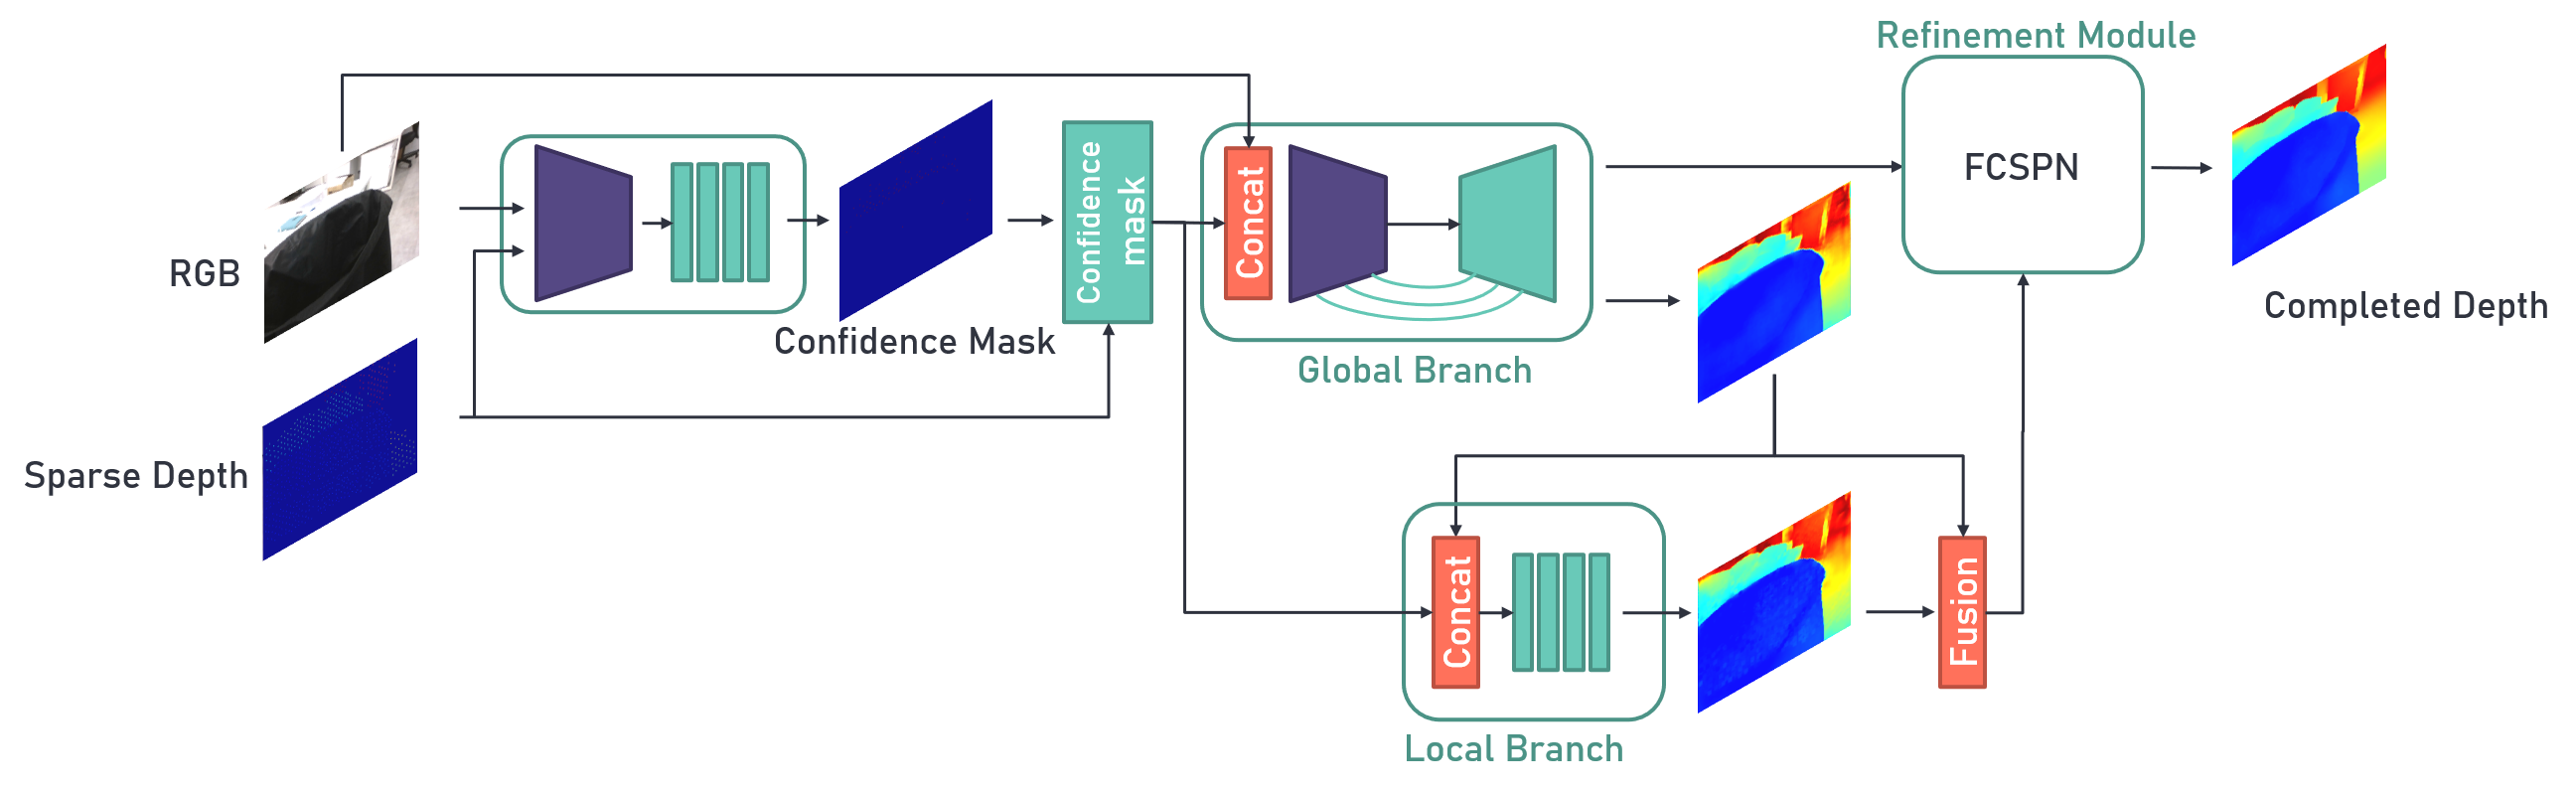
Fig. 3: Overall pipeline of the proposed method. A pair of color and sparse depth images is first concatenated and sent to a feature extractor to obtain the features $F$, which are used to generate spatially encoded features at different resolutions. The features $F$ are then up-sampled and fed into an MLP to estimate the confidence mask. The color image and the masked sparse depth are subsequently passed to a two-branch global-local network. Finally, a popular refinement technique, FCSPN, is applied for depth refinement to obtain the completed depth.
Given an RGB image $i$ and a depth image $d_{gth}$, we first generate a sparse depth map $d_s$ from $d_{gth}$. Stereo-Aware Augmentation aims to generate a pseudo sparse depth with occlusion errors, $\hat{d}$, to mimic the process of stereo calibration. Subsequently, we feed $i$ and $\hat{d}$ into the Confidence Estimation Module to estimate $d^{*}$ and the corresponding uncertainty $\sigma$. Eventually, during inference, occlusion errors in the sparse depth induced by dual-camera calibration are removed by the Confidence Estimation Module. The overall method is shown in Fig. 3. Note that our method does not require any dataset providing raw depth maps with occlusion errors.
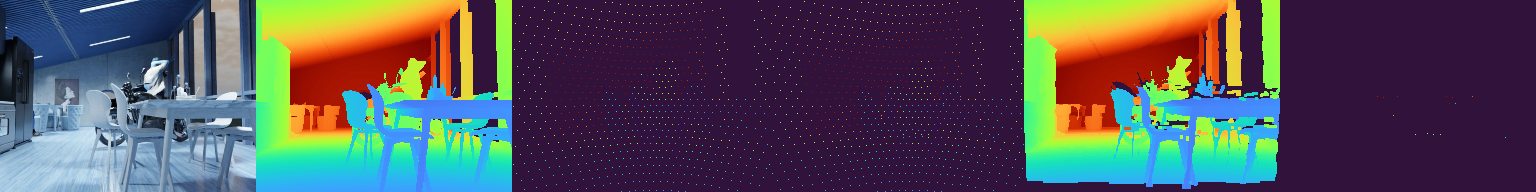
Fig. 4: Stereo-Aware Augmentation.
Stereo-Aware Augmentation As shown in Fig. 4, to generate the pseudo sparse depth with occlusion errors $\hat{d}$, we warp the depth image $d_{gth}$ using a 3D projection with proper extrinsic parameters. More specifically, we 1) project the ground-truth depth into 3D space; 2) perform a rotation around the x- or y-axis, which maps depth points from their original positions to new ones, and project them back to 2D, extracting a mask of the occluded points; 3) shift the occluded points; and 4) obtain the masked original sparse depth points. Note that an available intrinsic matrix and a well-selected extrinsic matrix are required.
Confidence Estimation Module The goal of the confidence estimation module is to provide an estimate of the reliability, or uncertainty, of the sparse depth associated with the input RGB image. In this article, we introduce an additional module into the existing depth completion network to estimate the confidence scores. This module is trained using loss functions that encourage retaining reliable sparse depth points. Inspired by [1], we model the confidence of the pseudo sparse depth with occlusion errors $\hat{d}$ by assuming a Gaussian distribution centered at the sparse depth $d^*$ with variance $\sigma^2$, the latter encoding the depth uncertainty. We then train the module with the sparse depth $d_s$ to regress $\sigma$ by minimizing the negative log-likelihood of this distribution.
Depth Completion Model The Confidence Estimation Module can then be cascaded with any depth completion model, such as EMDC [2], to obtain an improved sparse depth and achieve superior depth completion results.
Results
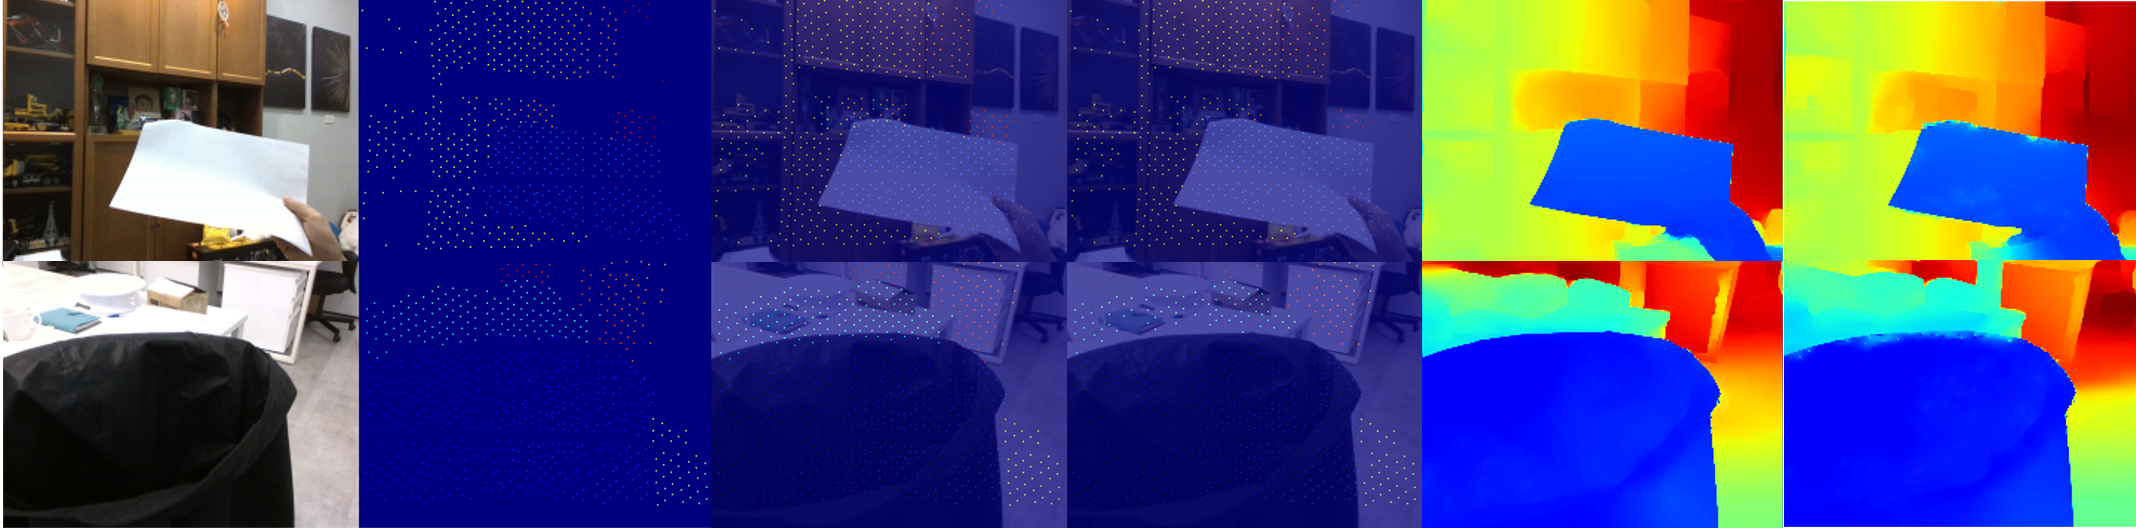
Fig. 5: Qualitative results of our method. EMDC tends to make mistakes in regions with occlusion errors. In contrast, our method learns a confidence mask to filter out occlusion errors and produces accurate, sharp object boundaries.
Qualitative results are shown in Fig. 5.
Conclusions and Future Work
The depth maps generated by sensors must often be coupled with an RGB camera to understand the framed scene semantically. Unfortunately, this process, together with the intrinsic issues affecting all depth sensors, yields noise and gross outliers in the final output. We observe that models suffer from occlusion errors caused by 1) spatial filtering, 2) erroneous measurements, and 3) stereo calibration. To tackle this, we propose Stereo-Aware Augmentation, an effective framework aimed at explicitly addressing this issue by learning to estimate the confidence of the sparse depth map, thus allowing the outliers to be filtered out.
References
[1] Conti, Andrea, et al. Unsupervised confidence for LiDAR depth maps and applications. IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), 2022.
[2] Dewang Hou, et al. Learning an Efficient Multimodal Depth Completion Model. ECCV Workshop, 2022.
[3] Andreas Geiger, et al. Vision meets Robotics: The KITTI Dataset. International Journal of Robotics Research (IJRR), 2013.